

 menu
|
|
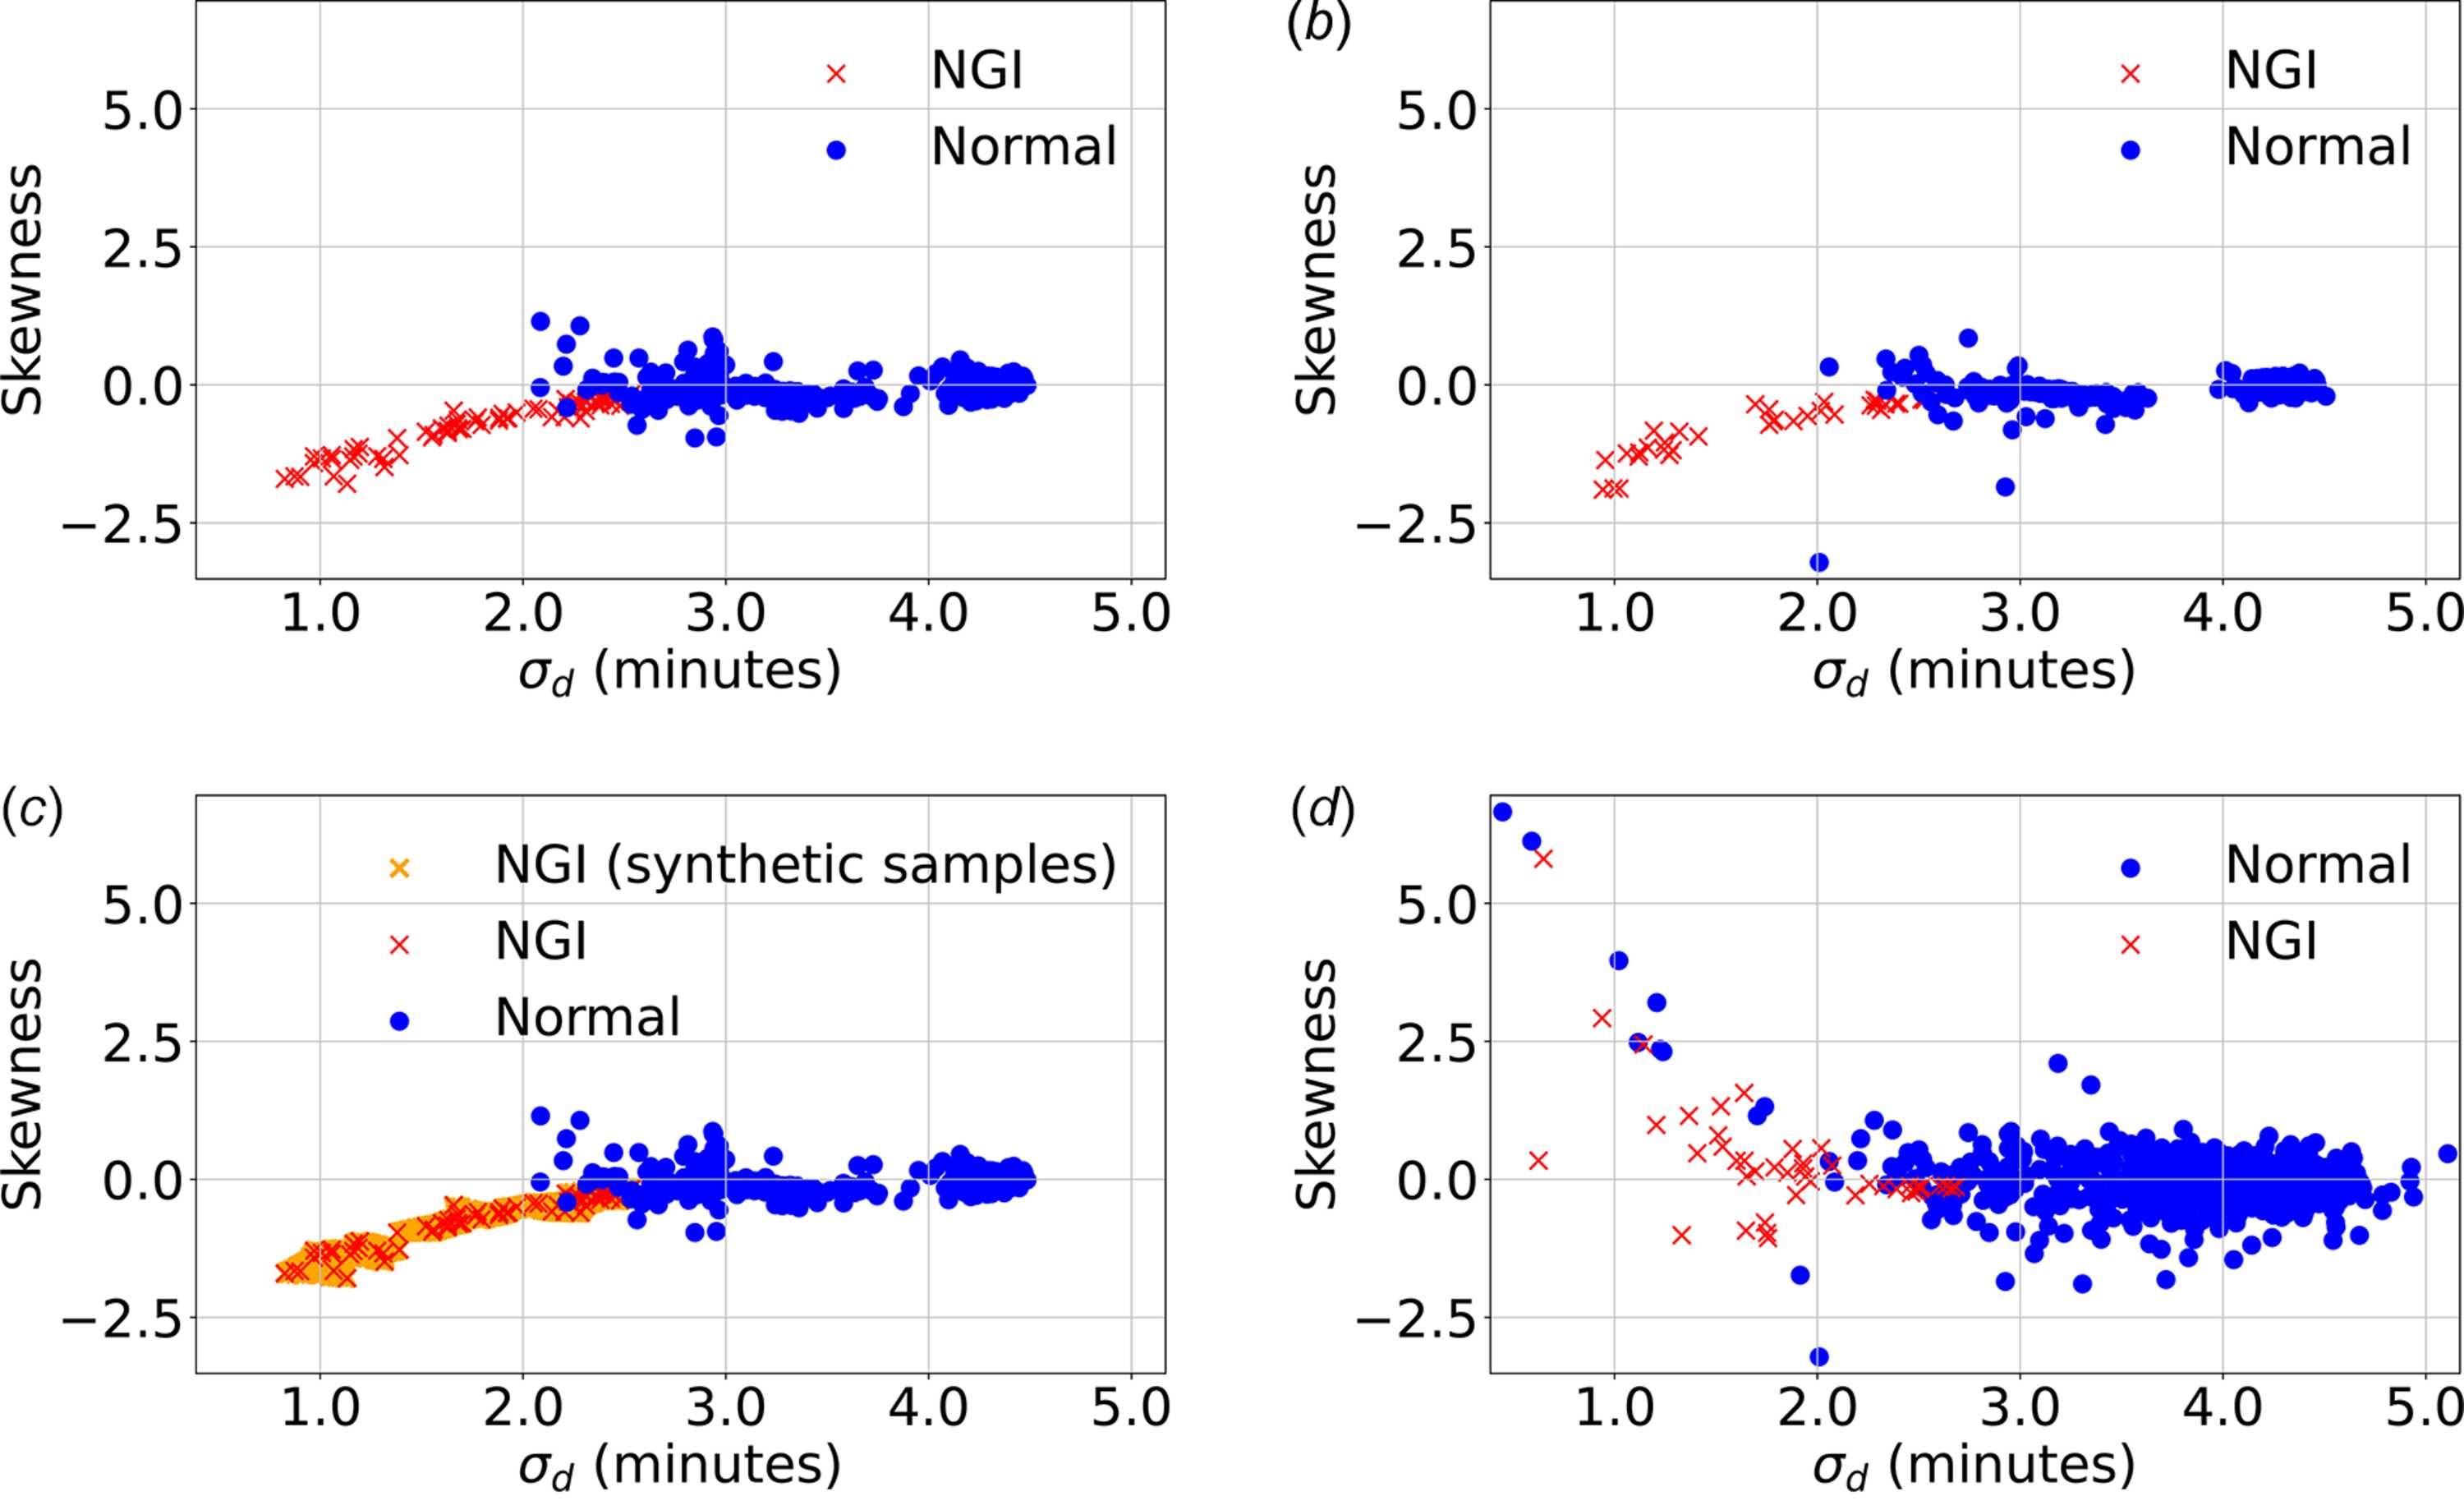
Figure 9
Visualization of data in feature space (standard deviation versus skewness). Panels (a) and (b) represent the training and test sets for DS-I, respectively. Both show similar distributions of samples in the feature space, as the training and test sets were randomly divided while maintaining the class ratio. Panel (c) displays the training data along with synthetic samples created using SMOTE. Panel (d) illustrates the distribution of new data after deployment, which shows a significant shift in distribution of NGI examples. |
 | JOURNAL OF SYNCHROTRON RADIATION |
ISSN: 1600-5775
 access